🔍 Read the full analysis: How Time-Series Models Are Opening New AI Use Cases In The Streamhouse on ThorstenMeyerAI.com

Get the latest gadgets delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
TL;DR
IBM and Confluent have made IBM time-series models available in Confluent’s Streamhouse, where Apache Flink can apply forecasting and anomaly-detection tasks to streaming data. The companies say the models run on CPUs in Confluent Cloud and on premises, but have not provided performance benchmarks, pricing or customer results.
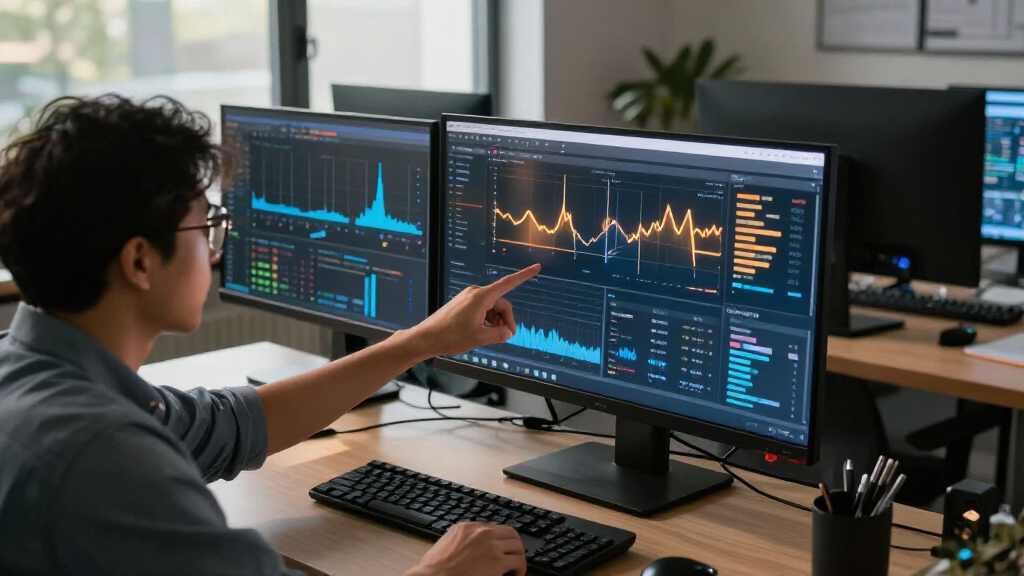
IBM and Confluent have added IBM time-series models to Confluent’s Streamhouse platform, allowing customers to apply forecasting and anomaly detection to streaming data through Apache Flink. The companies say the models are available in Confluent Cloud and on premises and run on CPUs, bringing predictive outputs into the same data flows used by operational systems.
Confluent says Flink users can prepare data and invoke model tasks using SQL, with the models offered as built-in functions for streaming workflows. In Confluent Cloud, the service is fully managed; organizations running on premises can use Confluent Platform for Apache Flink within their own infrastructure. The announcement does not specify regional availability or the supported model versions.
The models are designed to learn patterns from historical numerical data and apply them to new time series, such as measurements recorded over time. The companies describe this as a shared starting point that can reduce the need to train a separate model for every series. Depending on the task and deployment, teams may also fine-tune a model or combine its outputs with other data and business rules.
Examples cited by the companies include monitoring manufacturing processes, identifying unusual store activity, product planning, payment-signal assessment and trading-volume forecasts. These are potential applications, not documented customer outcomes. The source says the IBM model family has more than 50 million downloads, but gives no measurement period or comparison baseline for that figure.
Forecasts enter the streaming workflow
IBM time-series models are now available as native functions in Confluent’s Streamhouse. Apache Flink can apply forecasts and anomaly detection to live data.
Where models run
Teams can use the models in managed cloud or on premises, running on CPUs.
- Fully managed service
- Models invoked in streaming workflows
- Runs within customer infrastructure
- Uses Confluent Platform for Apache Flink
From events to action
Flink users can prepare data and invoke model tasks using SQL.
Bring in readings such as machine data, sales, orders or payments.
Add predictions or anomaly signals alongside incoming events.
Use outputs with current data, rules and operational decisions.
Potential applications
The companies describe possible uses, not verified customer outcomes.
Anticipate quality
Plant telemetry and quality measures could help forecast production outcomes.
Spot unusual activity
Anomaly signals could help teams assess store activity and product planning.
Assess signals
Streaming patterns could inform payment decisions while events are current.
Forecast volume
Time-series forecasts could support trading-volume planning.
What remains unproven
Availability does not establish that the models will fit a specific workload.
| Decision factor | Announcement detail |
|---|---|
| Forecast accuracy and latency | Benchmarks not provided |
| Business impact | Customer results not provided |
| Pricing and model versions | Not specified |
| Regional availability | Not specified |
Forecasts Closer to Operations
Putting forecasts alongside incoming events could help organizations surface a warning while there is still time to respond. A production-line signal, inventory change or unusual payment pattern may have less operational value if it arrives only after a periodic batch process has completed. With model outputs in a streaming workflow, an application or operator can evaluate them alongside current business context.
The CPU deployment claim may be relevant to teams that prefer not to provision dedicated GPU infrastructure for these workloads. But availability alone does not show that the models will meet a particular organization’s requirements. Teams still need to test accuracy, latency and resource use on representative data, and establish how predictions affect decisions. The announcement includes no independent benchmarks, measured business impact or named production customers.
Products Worth Considering

Logitech MX Brio Ultra HD 4K Webcam

Samsung Galaxy Tab A11+ Kids Edition, 128GB, Royal Blue

Amazon Kindle Scribe (16GB) with Premium Pen, Tungsten
As an affiliate, we earn on qualifying purchases.
From Streamed Data to Predictions
Time series arise when businesses record measurements or events over time, including machine readings, sales, orders, payments and inventory changes. Conventional forecasting may use separate models or periodic processing. Time-series foundation models aim to reuse patterns learned from historical data across new series and tasks, although results depend on the data and how a model is used.
Confluent describes Streamhouse as a platform for connecting, processing, governing and querying business data. Apache Flink processes and enriches data as it flows; the newly announced models add forecast or anomaly signals to that flow. The supplied material also describes a manufacturing scenario in which plant telemetry and quality measurements are used to forecast, four hours ahead, the share of ice cream tubs expected to meet a production target. It says an optimization process evaluates possible control settings, but gives no results or evidence that the scenario is deployed.
“Now available natively on Confluent, in the cloud and on premises, running on CPUs.”
— IBM and Confluent, in the announcement
Performance and Customer Evidence
The announcement does not report forecast accuracy, inference latency, throughput or resource use. It also provides no pricing, supported time-series formats, model-version details or conditions for fine-tuning. The download figure lacks a time period and baseline, so it cannot establish adoption growth or market share.
No customers are identified as using the integration in production, and no measured outcomes are supplied for the examples. For the manufacturing illustration, the source describes a forecast and evaluation of control settings but not the full decision process or any resulting change in output. The companies also do not explain how users should validate recommendations, handle poor-quality inputs or respond when data patterns shift.
Testing Across Deployment Setups
Confluent points prospective users to documentation for cloud and on-premises deployment. Organizations evaluating the feature will need to check those requirements and test it against representative workloads, including how predictions behave as new observations arrive. They will also need to determine whether outputs inform an application automatically, support an operator, or pass through additional business rules and review.
The supplied material names no further launch dates or product milestones. Published benchmarks, pricing and customer case studies with a stated time period and comparison baseline would help clarify the integration’s performance and practical reach. Until those details are available, the announcement establishes product availability, not demonstrated business results.
Key Questions
What did IBM and Confluent announce?
They made IBM time-series models available in Confluent Streamhouse for forecasting and anomaly-detection tasks on streaming data processed through Apache Flink.
Where can the models run?
The companies say the models are available in Confluent Cloud and on premises through Confluent Platform for Apache Flink. They say the models run on CPUs; the announcement does not detail regional availability or all deployment requirements.
Do the companies report customer results or benchmarks?
No. The supplied announcement includes no accuracy, latency or throughput benchmarks, named production customers, or quantified business outcomes. Its application examples are presented as possibilities.
What should organizations evaluate before using the models?
Teams should test the models on representative data and assess prediction quality, response time and resource needs. They should also decide how forecasts will be checked and used alongside business rules or human review.
Primary source: Hugging Face · via ThorstenMeyerAI.com