🔍 Read the full analysis: A Team-Friendly Guide To AI’s Time Horizon on ThorstenMeyerAI.com

Get the latest gadgets delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
TL;DR
A guide published by ThorstenMeyerAI.com on Nov. 18 explains how METR’s AI time-horizon measure can help teams choose work for AI agents. METR’s latest publicly listed result in the source is 185.9 minutes at 80% reliability for an early Claude Mythos Preview, but the benchmark has limits and its public results have not been updated since September.
ThorstenMeyerAI.com published a guide on Nov. 18 explaining how team leads can use AI “time horizons” to decide which tasks to delegate to AI agents. Drawing on METR’s public benchmark, the guide says the best measured model in the cited results completed tasks equivalent to about three hours of skilled human work in four out of five attempts, while warning that this is not a guarantee for ordinary workplace projects.
METR, an independent research nonprofit, defines a time horizon as the length of a task—measured by how long a skilled human takes—that an AI agent is predicted to complete at a specified reliability level. The guide focuses on the 80% threshold: the agent succeeds in four of five attempts. It stresses that the measure describes task difficulty, not how long the AI itself spends working. METR says agents can complete successful tasks several times faster than people.
In the results file cited by the guide, the leading public result is an early Claude Mythos Preview, dated April 7, 2026, with an 80% horizon of 185.9 minutes, or roughly three hours and six minutes. The reported confidence interval is wide: 97.3 to 398.5 minutes. The guide also lists GPT-4 at 0.89 minutes in March 2023, o3 at 29.98 minutes in April 2025, and GPT-5.2 at 66 minutes in December 2025.
The guide describes METR’s method as having skilled professionals complete benchmark tasks, then running AI agents against those tasks six times each and checking transcripts for cheating, which counts as failure. The current Time Horizon 1.1 suite contains 228 tasks, ranging from seconds to more than eight hours of human work. METR’s public results page was last updated Sept. 8, 2026, and is marked as no longer actively updated, according to the guide.
Using Horizons to Scope Team Work
The measure gives managers a more practical question than whether AI “can do” a task: how long would a skilled person need, and how often does the agent finish work of that difficulty? The guide recommends starting with short, bounded tasks that have clear acceptance checks, such as testable pieces of a larger ticket, rather than handing over an entire project based on a headline benchmark.
It also argues that teams should budget time for verification. An 80% horizon still implies failures in about one attempt out of five at the threshold, and the benchmark does not show that a model will perform equally well on every task of that length. Teams need to choose models for the work at hand and measure performance on their own tasks, the guide says, suggesting a quarterly review.
The operational stakes extend beyond speed. If review time, rework and missed errors are not counted, teams may overestimate the value of automation. The guide cites a 2025 METR trial in which experienced developers working with AI were 19% slower, despite believing they were 20% faster. It also cites a separate study where reviewers caught 31% of errors that required knowledge of task-specific rules to identify. These figures are presented as warnings about oversight, not as a universal forecast for all teams.
Products Worth Considering

Apple Watch SE 3 GPS + Cellular 40mm Smartwatch
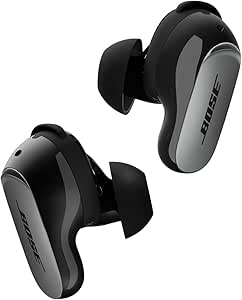
Bose QuietComfort Ultra Earbuds (2nd Gen), Wireless Noise-Cancelling Earbuds, Black

DJI Mini 4K Drone with 4K UHD Camera, Under 249 g
As an affiliate, we earn on qualifying purchases.
How METR Measures Task Length
METR’s benchmark is based on tasks completed by skilled professionals in software engineering, machine learning and cybersecurity. The guide says participants averaged about five years of relevant experience, and their working time was used to label each task’s difficulty. AI agents then attempted the tasks across multiple runs; success rates across task lengths were used to estimate the point where reliability falls below a chosen level.
The distinction between 80% and 50% reliability changes the practical reading. For the same Mythos Preview, the guide reports a 50% horizon of 1,044.8 minutes, or about 17.4 hours, compared with 185.9 minutes at 80%. METR cautions that measurements above 16 hours are unreliable with the current task suite, so the longer estimate is especially uncertain. The guide also says messier tasks cut the horizon by almost threefold in one METR comparison.
Those limits matter because benchmark tasks are more clearly specified than many real assignments, where requirements shift, dependencies are undocumented or success is hard to verify. A model’s result on a controlled task is evidence about a particular benchmark, not proof of its performance across a company’s full backlog.
“The task duration (measured by human expert completion time) at which an AI agent is predicted to succeed with a given level of reliability.”
— METR, as quoted in the guide
Limits in the Public Benchmark
The cited record has a wide confidence interval, and METR’s public results page is no longer actively updated. The guide reports that METR’s February–March 2026 Frontier Risk Report placed the labs’ internal frontier at at least three hours but under four hours at 80% reliability. That estimate is not a replacement for a current public benchmark, and the source material does not provide public measurements after April 2026.
It is also unclear how closely the benchmark’s cleanly specified tasks match the varied work of a particular team. The guide does not establish that a three-hour human task will receive the same success rate in a different model version, software environment or workflow. Nor does an average success curve promise a result for an individual task. The reliability level, task quality, available tools and review process all affect the outcome.
The source’s trend discussion says the horizon had doubled every three to seven months in the fitted historical data, but this is an extrapolation, not a confirmed schedule for future capability. The guide’s projections for an eight-hour workday span September 2026 to November 2027 depending on which years are included. Those dates should be read as model-dependent estimates, not established milestones.
Testing AI Against Local Tasks
The guide’s practical recommendation is for teams to turn larger assignments into hour-scale pieces with explicit acceptance checks, start with work that can be tested, and reserve time for human review. Managers should compare models on the same task types and track both successful completions and the effort needed to correct failures.
Teams can then repeat those evaluations regularly, with the guide proposing a quarterly cadence, to see whether performance changes on their own work. The next public milestone is not specified in the source: METR’s results page had stopped active updates, and no later public benchmark result is cited. Until new measurements are released, the three-hour figure remains a dated result with substantial uncertainty—not a promise about what AI agents can reliably handle next.
Key Questions
What does an AI time horizon measure?
It estimates the human working time required for tasks an AI agent can complete at a specified reliability level. It does not mean the AI spends that amount of time working.
What is the latest public result cited in the guide?
The guide cites an 80% time horizon of 185.9 minutes for an early Claude Mythos Preview dated April 7, 2026. Its reported confidence interval is 97.3 to 398.5 minutes.
Does a three-hour horizon mean an agent will finish every three-hour task?
No. The 80% figure is an estimated success level across benchmark tasks of that difficulty, not a guarantee for any individual task. The guide also warns that real work can be messier than METR’s benchmark tasks.
How should a team use the measure?
Use it as a rough planning aid, then test agents on local tasks. The guide recommends breaking work into bounded pieces with clear acceptance checks and including human review and correction time in estimates.
Are the guide’s forecasts for an eight-hour workday confirmed?
No. The guide’s September 2026 to November 2027 range depends on historical trend fits and the years selected. It is a projection, not a confirmed capability date.
Source: ThorstenMeyerAI.com